Preventing AI Hallucinations in SEO Content
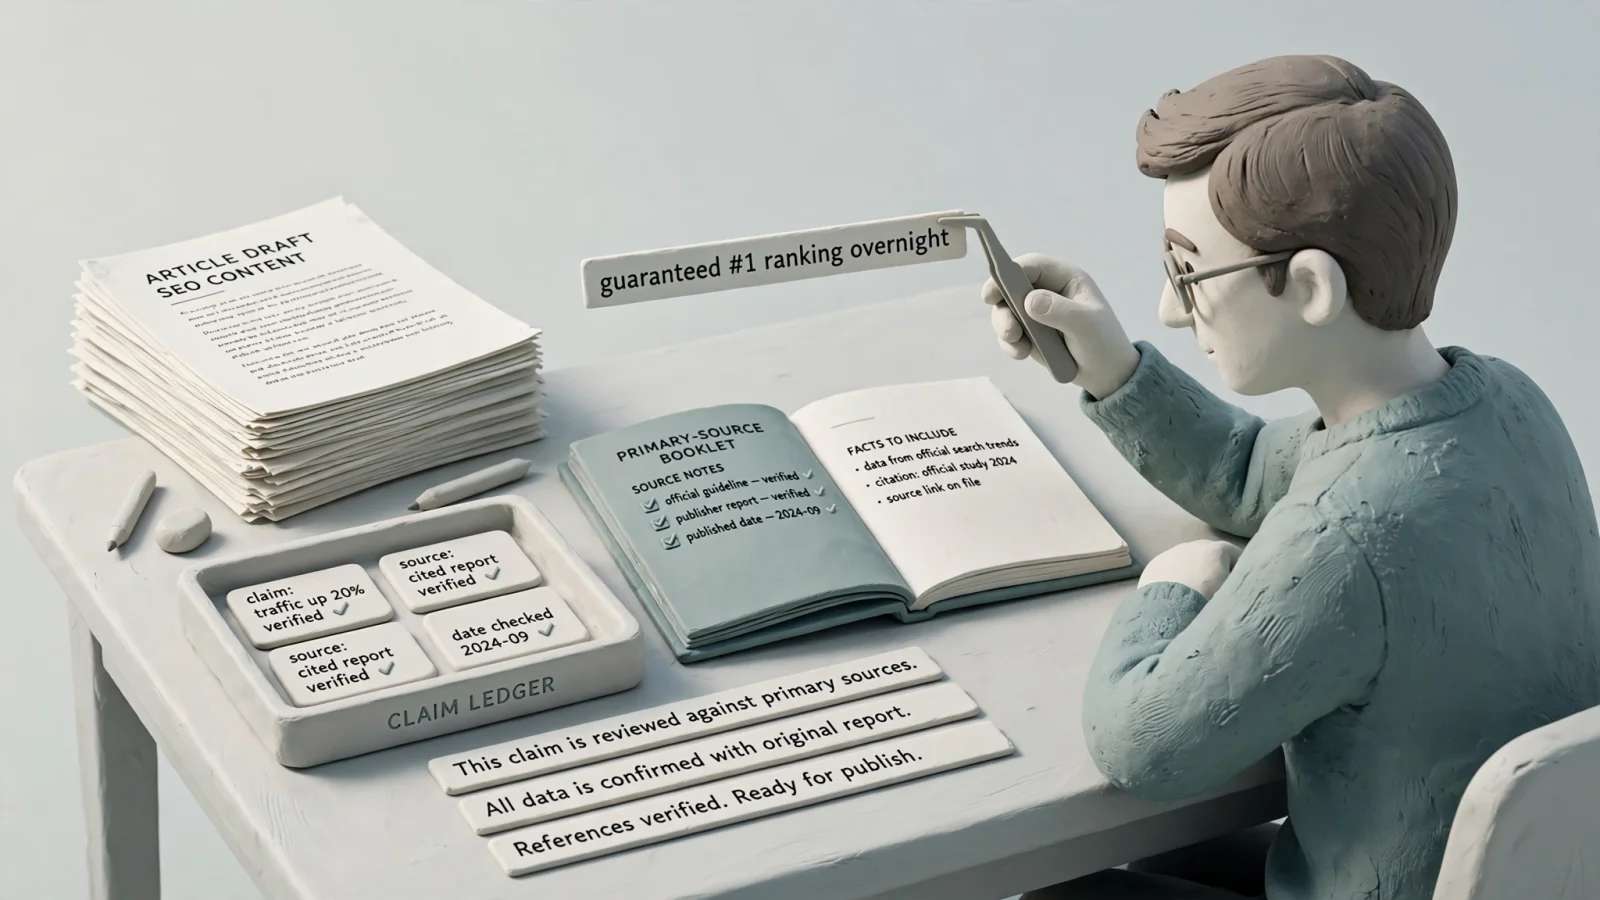
Imagine reading a generated paragraph about server response times where the prose reads perfectly. The text provides a precise load-time benchmark and includes a credible-looking source link pointing to a recognized hosting provider. You click the link, and while the page resolves and the topic matches, the specific benchmark does not exist anywhere on the domain. The model produced a persuasive, grammatically flawless sentence that happens to be entirely false.
Asking the model to try harder will not solve this behavior. Managing factual gaps requires a disciplined publishing workflow rather than a promise of flawless text generation, which is exactly the discipline RankPine builds into automated content operations. We treat preventing AI hallucinations in SEO content as a supply-chain challenge. You control the risk by introducing source packs, claim ledgers, citation checks, abstention rules, and selective human review before a draft ever reaches your production site.
Why Fluent AI Drafts Require Independent Evidence
The danger of an unverified draft lies in its confidence, because a model will write an invented statistic with the exact same authoritative tone it uses to state a widely accepted fact.
Identifying Hallucinations in SEO Content
An SEO hallucination extends beyond obvious nonsense. A 2024 NIST report on generative AI risks uses the precise term "confabulation" to describe confidently presented content that is erroneous or false. In search marketing copy, this failure takes several specific forms.
A model might fabricate a percentage without any original study behind it, or invent a quote and attribute it to a real industry expert without a verifiable transcript. Generation tools frequently suffer from scope drift, presenting a finding from a narrow academic study as a universal rule for all businesses. Stale information poses another frequent risk, as models confidently describe software features, pricing tiers, or algorithm updates that changed years ago. The system might also generate a citation mismatch where the draft includes a real link to a real page, but that page fails to support the specific conclusion the article draws from it.
Separating Tone from Accuracy
Prompting a model to "be highly accurate" does not grant it access to new facts. It only instructs the system to adopt a highly assured tone.
Research from OpenAI on why language models hallucinate explains that common evaluation practices often reward models for guessing rather than acknowledging uncertainty. A reliable workflow requires the opposite approach. Acknowledging a missing fact is vastly preferable to confidently providing an incorrect one, meaning your system needs to permit the model to abstain, say "unknown," or omit a detail entirely when evidence is absent.
Recognizing Vulnerabilities in Search-Driven Content
Search content creates distinct vulnerabilities that short-form social copy or internal memos avoid. Its format and subject matter create more opportunities for unsupported claims.
Long-Form Pages Multiply Factual Claims
A standard two-thousand-word article contains dozens of individual assertions. The text includes definitions, dates, numerical comparisons, step-by-step technical instructions, and implied conclusions. Each noun-verb pairing that asserts a fact represents another potential failure point. Because open-ended prompts encourage a model to fill all available space, a system left to its own devices will populate a long layout with plausible-sounding filler details to meet a length requirement.
Managing Fast-Changing Search Topics
Search queries often target rapidly changing environments. Users look for current software prices, newly enacted regulations, recent hardware specifications, or the latest industry research. A model relying exclusively on its training data struggles to provide accurate answers about a product version released last week, and when a topic requires up-to-date domain expertise, the risk of a confident error rises sharply.
Containing Errors Before They Spread
One unsupported statement rarely stays contained on a single page. A fabricated statistic in your main text often becomes an H2 heading, which then gets pulled into a featured snippet. The same false claim gets referenced in internal links from derivative pages, repurposed into newsletter copy, and shared on social media.
Classifying risk before drafting helps contain this spread. Stable, universally accepted definitions require less scrutiny than medical claims, financial advice, security protocols, technical instructions, or direct product comparisons.
Building an Evidence-First Drafting Workflow
A reliable publishing cadence starts before the prompt. You build factual reliability by separating the research phase from the drafting phase.
Classifying Topic and Claim Risk
Start by determining what kind of claims your article requires. Identify whether the piece relies on stable concepts, current pricing, specific statistical findings, or experience-based recommendations. Distinguish clearly between a sourced fact, an editorial inference, and a preference. For example, a statement like "Bounce rate measures single-page sessions" operates as a stable fact, whereas claiming "You should optimize landing pages first" functions as a recommendation.
Assembling a Pre-Draft Source Pack
Collect approved evidence before you ask the model to write. Build a source pack containing official documentation, government or standards-body material, original research, first-party product pages, and company filings.
Treat search-result snippets as discovery aids rather than final evidence. Record each source's exact title, URL, publication date, and the specific passage that matters, then pass this structured data to the model.
Mapping Claims and Permitting Abstention
Track this evidence using a structured claim ledger, which gives a solo founder or lean marketing team a manageable way to oversee content quality.
| Claim ID | Draft Claim | Source | Evidence Location | Status |
|---|---|---|---|---|
| C-01 | Precise factual statement | Source URL | Methodology section | Verified |
| C-02 | Software feature capability | Developer documentation | API reference | Needs Review |
| C-03 | Editorial advice | None required | Author reasoning | Recommendation |
| C-04 | Market statistic | Industry report | Executive summary | Hold |
Pass this ledger, the source pack, and your editorial brief to the model. Instruct the system to use only the approved sources and to identify the supporting source for every factual statement. Set an abstention rule: if the source pack lacks support for a detail, the model writes "NEEDS EVIDENCE" rather than guessing. If you want to scale this tracking process without managing spreadsheets, you can review our guide on auto generating blog posts with real links.
Verifying Citations at the Claim Level
Citations build trust only when they withstand scrutiny, because a URL formatted as a hyperlink proves nothing on its own.
Distinguishing Citation Presence from Validity
The NIST report explicitly warns that generated citations might falsely appear to justify an answer. Editors need to differentiate between a link appearing in a draft and a link genuinely supporting the adjacent sentence.
Automated generation tools frequently produce citation-shaped objects where the anchor text looks natural, the URL format appears correct, and the domain belongs to a recognized organization. However, none of these surface details confirm that the page contains the cited information.
Checking Entailment, Scope, and Authority
Evaluating a citation requires a specific sequence of steps. First, check whether the URL resolves to a live page, and then confirm the source exists under the stated title and organization.
Next, verify entailment. The source needs to support the precise conclusion the draft makes, rather than merely discussing the broad topic. Preserving the source's original scope prevents a report surveying enterprise technology companies in Europe during 2023 from being presented as universal truth for small local businesses in 2026. As a result, every statistic you retain needs to name the original reporting organization and note the year.
Adding Contradiction and Freshness Checks
Run automated checks across the complete draft to catch structural errors by flagging broken links, duplicate URLs, and factual claims missing a source ID. Compare numbers and dates for consistency to ensure one section does not claim a process takes three steps while a later section lists five.
Automation handles this triage efficiently. For a broader look at how software tackles these initial checks, see our breakdown of automated fact-checking for AI-generated articles. Keep in mind that machine triage flags potential problems, leaving the final editorial decision to a person who confirms that the cited text aligns with what the article claims it means.
Using RAG and Automation as Safeguards
Connecting the system to external data serves as a common technical solution to model hallucination. While this helps, it does not remove the need for oversight.
How Retrieval-Augmented Generation Helps
Retrieval-augmented generation, often called grounding, allows a model to retrieve information from relevant sources before drafting an answer. Google's documentation on AI optimization explains that its own generative features use this technique to retrieve relevant, up-to-date web pages from its Search index, improving the quality, accuracy, and freshness of responses.
Grounding directly attacks the problem of stale training data by giving the model access to current software documentation, recent news, and live pricing.
Recognizing the Limits of Grounded Sources
Access to a source does not guarantee correct interpretation, as a retrieved document might be outdated or irrelevant to the specific user query. The model might apply a highly specific technical finding outside its original context, or it might cite a weak secondary blog post beside a massive, definitive claim that requires primary research.
RAG acts as a risk-reduction layer that provides better raw materials, but the system still relies on editorial rules to construct a sound argument. If you are comparing different platforms offering these capabilities, our hub on purchasing an automated SEO content subscription explains how to evaluate their underlying architectures.
Automating Triage Rather Than Judgment
Assign specific tasks to your automation layer and reserve others for human review. Automation excels at link resolution, detecting missing citations, matching repeated numbers, finding conflicting dates, and flagging overconfident wording like "guaranteed" or "always."
Automation cannot easily judge authority. A script identifies whether a link works, but a person needs to decide whether a particular vendor blog operates as a trustworthy source for a competitive market share statistic. Automating the gathering and sorting of evidence frees your attention to evaluate its quality.
Establishing a Publishing Gate for Daily Content
Consistent publishing drives organic growth, while publishing unverified claims destroys trust. Reconciling these two outcomes calls for a disciplined gatekeeping system.
Using Evidence Statuses for Publishing Decisions
A reliable workflow categorizes every generated draft into one of five distinct outcomes. An article becomes ready to publish when every claim matches an approved source and all links resolve. A piece qualifies as safe after you rewrite absolute claims into conditional ones and explicitly label recommendations as editorial opinions. A draft enters a missing evidence state when it triggers an abstention rule. A piece demands human review if it touches on sensitive topics or utilizes complex original research. Finally, a draft becomes entirely unpublishable when the central premise relies on a fabricated concept or repeatedly fails citation checks.
Reviewing High-Risk Content by Exception
Reviewing by exception lets you scale your operation without reading every word of every evergreen definition post.
Prioritize human oversight for legal, financial, medical, and security claims. Set up manual approval for product comparisons, exact statistics, performance guarantees, and purchase recommendations, while routing any draft with weak, conflicting, or unusually old sources directly to a hold queue. While automated scheduling keeps your calendar full, blind automation forces unverified text live merely to meet a quota. For practical implementation steps, read our guide detailing the SEO content workflow for busy founders.
Monitoring Published Articles Over Time
Evidence requirements continue after a page goes live, making it useful to keep your source pack and claim ledger attached to the published URL in your content management system.
Recheck these pages when a cited primary source updates its methodology or a software vendor releases a new version. If you notice search performance dropping or users leaving feedback about confusing steps, revisit the evidence ledger. Track your citation validity rate and unsupported claim rate, because the frequency with which your system holds a draft helps distinguish output volume from underlying content quality.
Turning Accuracy Into a People-First SEO Standard
Google's guidance consistently warns against creating content primarily to manipulate rankings, noting that high page volume does not automatically make a website higher quality. Foundational SEO still matters, while factual reliability remains central to useful content.
Following a Reusable Anti-Hallucination Checklist
Apply this standard checklist to every draft before it leaves the hold queue:
- Require a primary source for every nontrivial number, percentage, or date.
- Open and verify every external link manually or through a resolution script.
- Confirm the cited page supports the exact sentence rather than the general topic.
- Preserve the location, population, timeframe, and qualifiers of the original research.
- Remove all invented quotes, unverified transcripts, and unsupported recommendations.
- Scan the document for internal contradictions and stale product details.
- Place any claim that lacks evidence on hold.
Keeping Generative-Search Claims Grounded
The qualities that build trustworthy organic content also help that content perform in generative search features. Clear topic focus, direct answers, accurate claims, and relevant citations serve both traditional crawlers and AI retrieval models.
Avoid treating AI-search optimization as a formatting trick. Excessive keyword variations, artificial chunking, or special file formats will not save a page built on false premises, so optimize for usefulness by providing original analysis grounded in verifiable facts.
Managing Evidence at Scale
Citations alone fail to prevent hallucinations, as a model can easily generate a perfectly formatted citation that points to an irrelevant page. While RAG improves freshness, it still requires entailment checks to ensure the retrieved data matches the drafted claim. When an AI system cannot find evidence, it needs to abstain, omit the detail, or route the draft to a human editor rather than guessing.
Managing this process manually drains the time you need to run your business. RankPine automates the heavy lifting of SEO content creation while maintaining a disciplined research and citation workflow.
For consistent organic growth without turning every article into a manual fact-checking project, use RankPine to analyze market trends, generate cited content, and maintain a daily publishing schedule while securely holding unsupported claims for review instead of forcing them live. Start automating your SEO content workflow today at RankPine.