Writing Authoritative Content for AI Search
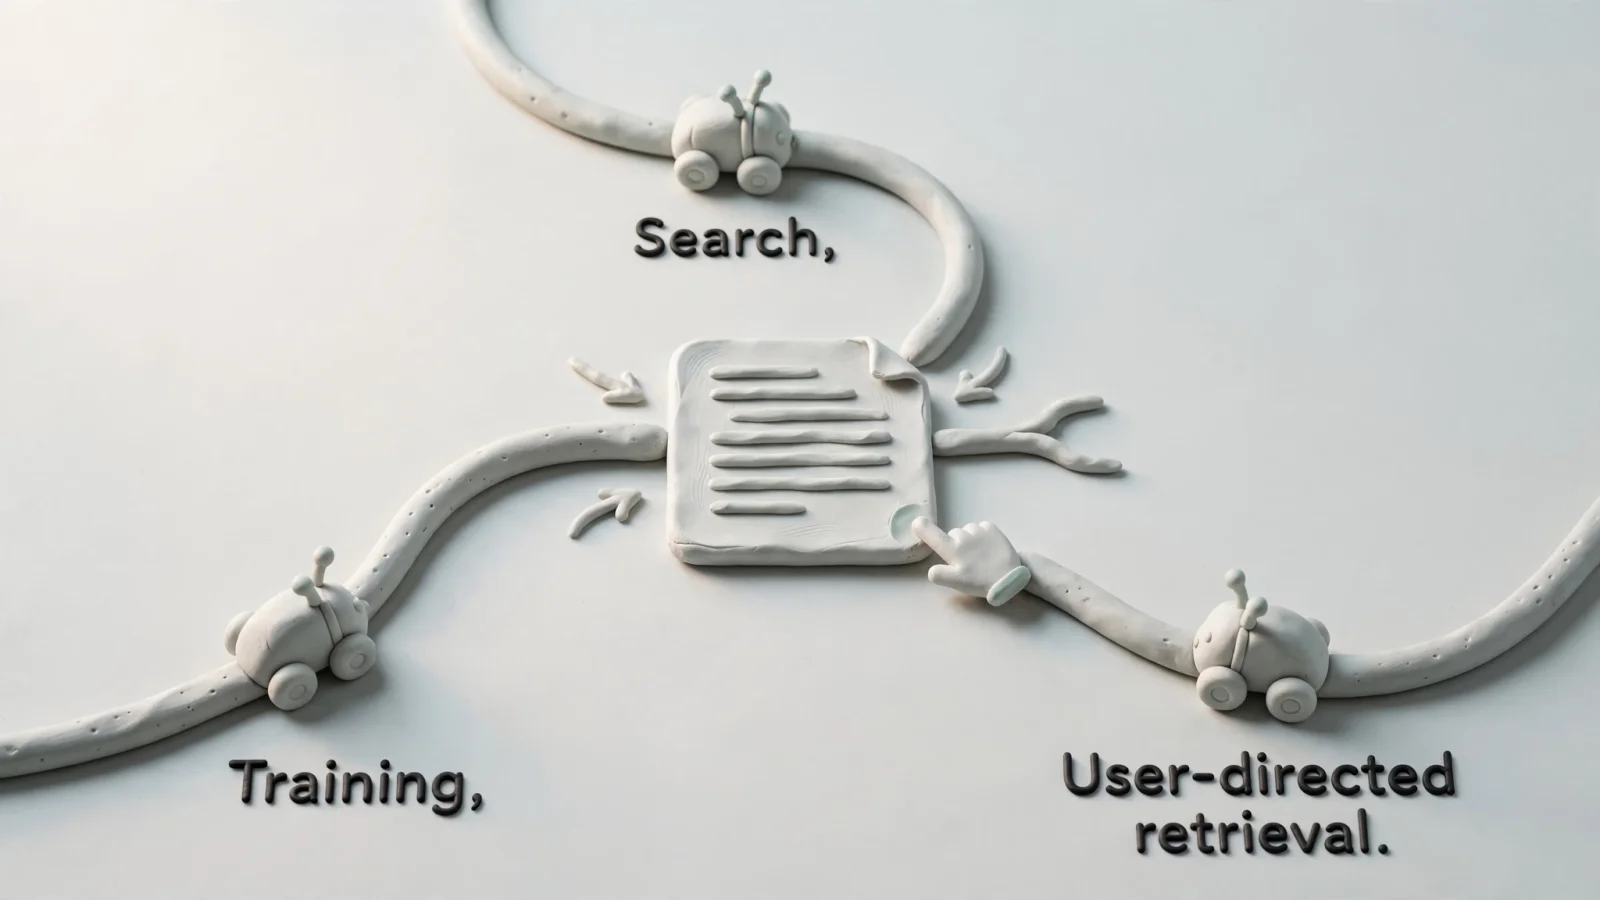
The term “LLM scraping” gets thrown around as a single uniform process, but it describes several different ways artificial intelligence systems interact with website data. Whether a crawler is gathering text to train a massive language model or pulling a live page to answer a specific user prompt, making your site useful to these systems requires more than flipping a switch in a configuration file. You need content that is accessible, original, and easy for both algorithms and humans to verify. RankPine approaches this challenge by managing a complete research and publishing workflow, turning validated topics into source-led articles every day rather than chasing unproven citation hacks.
How AI Systems Collect Website Data
Before adjusting your site configuration or changing how you write, you have to separate the different types of AI data collection. Artificial intelligence providers do not use a single bot to perform every task, dividing their web fetching into distinct categories based on what the system intends to do with the information.
Training crawlers collect vast amounts of public data to teach language models how to predict text, recognize patterns, and recall broad facts. Search crawlers index pages so an AI search engine can surface them later in response to relevant queries. User-directed retrieval tools fetch a specific page because someone dropped a URL into a chat interface or asked a connected plugin to summarize a live article. These are distinct operations with different business implications.
| Crawler Type | Primary Purpose | Impact on Your Website |
|---|---|---|
| Model Training | Ingests text to build the underlying capabilities of a large language model. | Content becomes part of the model's generalized knowledge, rarely resulting in direct traffic or links back to the source. |
| AI Search | Indexes pages to populate real-time generative answers. | Content can appear as a cited reference or linked snippet in AI search results, potentially driving direct visits. |
| User-Directed | Fetches a specific URL provided by a human user in a chat session. | Allows users to interact with your specific page content via a chatbot interface; traffic depends entirely on user prompts. |
OpenAI uses separate crawlers for distinct tasks. For example, the OpenAI publisher documentation identifies GPTBot as a crawler for content that may be used to train its generative AI foundation models and OAI-SearchBot as a crawler that surfaces websites in ChatGPT search. Because the settings are independent, a site can allow OAI-SearchBot for search results while disallowing GPTBot to indicate that its content should not be used for training.
Crawler Access Is Not a Citation Guarantee
Allowing a bot to read a page only makes that page eligible for the next step. It does not establish the page's authority or force an AI platform to quote your text, which means the technical ability to fetch a URL is merely the baseline requirement for participation in search results.
For features like AI Overviews, the Google AI optimization guide says a page must be indexed and eligible to appear in Google Search with a snippet, and its site must also be included in Search generative AI features in Search Console. The guide also explains that Google’s generative AI features retrieve relevant, up-to-date pages from its Search index and review the information on those pages when generating responses.
Attempting to force this selection through technical formatting hacks wastes resources. Google explicitly states that special schema markup, artificial page lengths, and tiny content chunks are unnecessary for its generative AI features. Providing an llms.txt file also changes nothing for Google Search visibility, despite claims that it acts as a shortcut to AI rankings.
The structural work involves basic public availability. Ensure your server responds quickly under load, and review your robots.txt directives to explicitly allow the specific search bots you want to reach your site. A firewall or content delivery network can mistakenly flag AI search crawlers as malicious automated traffic. Once the technical pathways are clear, the focus shifts entirely to the quality and distinctiveness of the information on the page.
What Makes Content Worth Referencing
Authoritative content goes beyond confident wording, aggressive keyword placement, or a lengthy author biography to offer useful, distinctive information supported by clear evidence. When an AI search feature evaluates a page, it looks for signals that the text provides something beyond a paraphrase of other available results. If your article only summarizes the top five ranking pages, it contributes nothing new to the index, whereas a specific, well-supported example gives both human readers and automated systems a distinct resource to consult.
For lean marketing teams and solo founders, this means publishing material rooted in daily business operations. A real workflow you developed to solve a client problem carries more weight than a generic list of industry tips. A customer question answered with detailed product knowledge provides specific constraints and solutions that AI systems can extract as high-confidence facts.
When writing a comparison, establish explicit decision criteria rather than listing features. For example, comparing two software tools based on their "deployment speed for enterprise teams with legacy databases" is far more useful than stating one is "faster" than the other. If a methodology failed in practice, document the observed lesson and state the limitations clearly. AI models evaluating text for grounding purposes benefit from explicit boundaries on factual claims.
Accurate authorship provides necessary accountability. Apply bylines to people with relevant experience, and ensure those biographies reflect their professional history. Never invent a credential or claim firsthand knowledge the author lacks. Trust is built through verifiable specifics.
Build a Source-Led Article Readers Can Verify
Writing authoritative content for LLM scraping requires a systematic approach to topic selection, structure, and evidence. A page designed to be cited must anticipate what information is missing from current search results and provide a structured answer that stands up to scrutiny.
Follow a clear editorial sequence to build verifiable content:
- Choose one real reader problem. Connect the topic directly to your audience and your business's expertise. Avoid creating a separate page for every phrasing variation of the same question. Consolidate related queries into a single resource that thoroughly resolves the underlying issue.
- Answer the main question early. A concise opening answer followed by supporting detail creates a reader-friendly structure. Do not hide the primary conclusion behind paragraphs of background information. State the fact, then explain the mechanism.
- Add original constraints or frameworks. Bring in first-hand experience, a concrete workflow, or a useful decision framework. If the draft only summarizes the current search results, narrow the topic or add a meaningful point of view based on observed industry data.
- Make claims traceable. Link factual assertions to sources that directly support them. For statistics, include the source name, the report title or publication, the year, and the relevant population or conditions. Mark estimates and editorial judgments clearly. Omit a number that adds decoration rather than decision value.
- Structure content for human readers. Use descriptive headings, sequential steps, comparison tables, and clear caveats where they make the subject easier to understand. Keep important information available as plain text. Avoid forced micro-chunking or padding the page to hit an arbitrary word count.
If automation materially shaped the article, explain that process where it would help readers understand how the content was created. Transparency about the tools used to aggregate data or format research builds credibility. Structure the entire piece around logical progression, ensuring each paragraph carries the explanation forward rather than repeating the same point with different vocabulary.
Understanding the GEO vs SEO differences helps clarify this approach. Traditional search engine optimization often focused on keyword placement and backlink profiles, whereas generative engine optimization demands high-information density, clear causal explanations, and distinct data points that an AI can confidently extract and cite as fact.
Publish Consistently Without Creating Commodity Content
Quality and purpose matter more than cadence. A daily publishing schedule builds a compounding library of resources, but only if each new page serves a distinct purpose. Publishing repetitive, inaccurate, or low-value pages triggers spam filters and alienates readers.
Google's guidance says using generative AI or similar tools to generate many pages without adding value for users can violate its scaled-content-abuse policy, as explained in the Google Search's guidance on using generative AI content. For a continuous publishing operation, that makes maintaining editorial standards across a high volume of output a practical priority. The guidance also calls for manually reviewing and fact-checking AI-generated content for accuracy and trustworthiness before publication.
RankPine provides a disciplined system for maintaining this standard at scale. The platform researches market and competitor opportunities, identifying long-tail topics with realistic ranking difficulty, which prevents a site from wasting resources on heavily saturated keywords. RankPine then generates and publishes one researched, citation-backed article directly to your CMS each day. By handling the heavy lifting of drafting and structuring evidence, this automated workflow allows founders and niche site builders to scale organic traffic without spending their entire week writing.
Consistent publishing works best when paired with editorial oversight. Treating RankPine's output as a highly capable first draft and applying a quick editorial review to verify sources acts as a strong safeguard against commodity content. Checking bylines and confirming that the advice aligns with your brand perspective ensures the page provides value without cannibalizing existing articles on your site. Using a hands-off system to scale organic traffic without writing content still requires a strategic approach to topic selection.
After publishing, measure the results using the right tools. Use Search Console’s generative AI performance reporting where available to see how often your pages appear in AI Overviews. Rely on ordinary web analytics to assess the traffic and conversions that impact your business. Tracking visibility in AI interfaces helps refine your topic strategy, allowing you to focus on the technical queries or specific product comparisons that these systems favor. Implementing a system for tracking brand mentions in AI chatbots provides further insight into how language models interpret and categorize your company's information.
Frequently Asked Questions About LLM Scraping
Crawler access can make your content available to artificial intelligence systems, but it does not establish authority or guarantee a citation. The following answers clarify common misconceptions about how AI platforms interact with website data.
Is writing for LLM scraping the same as SEO?
Writing for AI search overlaps heavily with established SEO practices, but the emphasis shifts. Both disciplines require indexable pages, clear site architecture, and fast load times. However, optimizing for language models places a higher premium on original data, explicit definitions, and traceable citations. While traditional SEO might reward a highly linked page that aggregates common knowledge, AI search algorithms often look for the primary source of a specific fact or a highly structured comparison that answers a complex prompt.
Are AI-training bots and search bots the same?
They are distinct systems designed for entirely different tasks. Training bots collect massive datasets to build the foundational capabilities of a language model. Search bots index specific pages so a live search feature can surface them to answer real-time queries. Major AI providers document these bots separately, allowing you to block training ingestion while remaining eligible for search visibility.
Does llms.txt help Google AI search?
Google specifically states that providing an llms.txt file does not affect visibility or rankings in Google Search. While some developers advocate for the file format to help automated systems parse site documentation, it is not a requirement for appearing in AI Overviews, nor does it act as a shortcut to authority.
Does crawler access guarantee an AI citation?
Allowing a crawler to fetch your page only makes the content eligible for consideration. AI search features select sources based on the relevance, accuracy, and distinctiveness of the information. Technical access is the prerequisite; the quality of the evidence and the clarity of the writing determine whether the system uses the page in its output.
Does publishing daily improve AI visibility or rankings?
A daily schedule builds a larger footprint of indexable pages, increasing the total number of opportunities a site has to rank or be cited. However, the cadence itself is not a ranking signal. Publishing thirty highly repetitive, generic pages will harm a site's reputation and trigger scaled-content penalties. Publishing thirty distinct, fact-checked, source-led articles expands a site's topical authority and provides more high-quality material for AI systems to reference.
RankPine automates the research and production of citation-backed, SEO-optimized articles, delivering one publish-ready post to your CMS every day. Start building topical authority on autopilot at RankPine.